离策略RL在LLM中对齐中具有高样本效率和容忍数据陈旧的优势
Off-policy RL offers high sample efficiency and tolerance to data staleness for LLM alignment
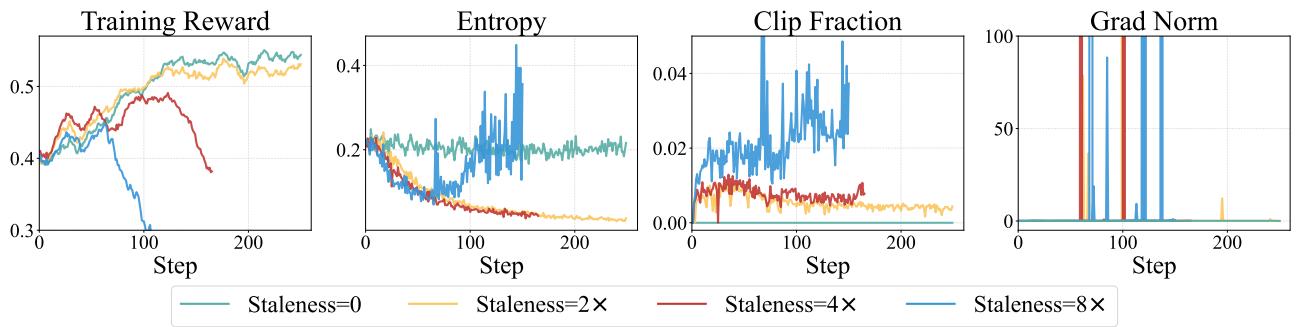
离策略训练面临优化不稳定、策略熵急剧下降和训练崩溃的挑战
Off-policy training suffers from unstable optimization, sharp entropy decline, and training collapse
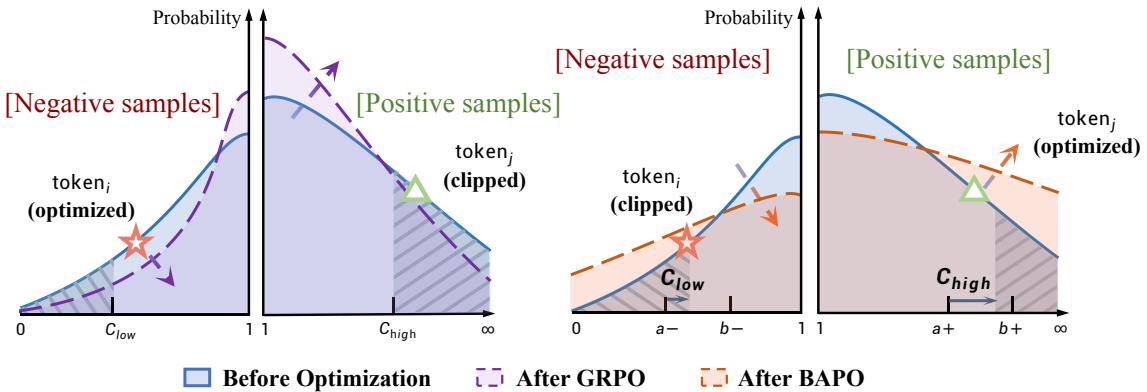
现有PPO-like方法使用固定对称裁剪,无法适应不同数据分布
Existing PPO-like methods use fixed symmetric clipping, unable to adapt to different data distributions